

Software Engineer in Machine Learning: Roles, Skills, and Career Path
What Does a Machine Learning Software Engineer Do?
A machine learning software engineer builds the systems that allow computers to learn from data and make predictions or decisions. The role combines software engineering with machine learning, turning models and experiments into reliable features that can be used by real people and businesses.
Machine learning is used in many familiar products, including recommendation systems, fraud detection, voice assistants, image recognition, and search. Behind these features are engineers who develop the software, data pipelines, and infrastructure needed to make machine learning work at scale.
What Is a Machine Learning Software Engineer?
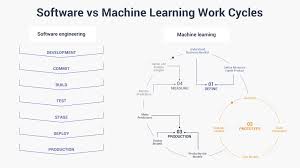
A machine learning software engineer applies engineering principles to the full lifecycle of machine learning products. This may include preparing data, building and integrating models, deploying services, and monitoring performance after release.
The job title can mean different things from one company to another. Some roles focus heavily on model development, while others emphasize production software, infrastructure, or data systems. In general, the role sits between traditional software engineering and applied machine learning.
Typical Responsibilities
Responsibilities vary by team and product, but may include:
- Designing, building, and maintaining software that uses machine learning models
- Preparing data for training, testing, and inference
- Integrating models into applications, APIs, or backend services
- Developing tools and pipelines for training and deploying models
- Testing model behavior, software quality, and system reliability
- Monitoring production systems for errors, latency, and changes in model performance
- Working with data scientists, product managers, designers, and other engineers
- Documenting technical decisions and communicating tradeoffs
In many cases, the work does not end when a model is trained. The model must also be served efficiently, updated when data changes, and evaluated to ensure it continues to meet product requirements.
Skills and Technologies
Programming and Software Engineering
Python is widely used in machine learning, but engineers may also work with languages such as Java, C++, Go, or JavaScript. Strong software engineering skills matter regardless of language. These include writing readable code, designing maintainable systems, testing changes, using version control, and troubleshooting production issues.
Machine Learning Fundamentals
Machine learning software engineers benefit from understanding common model types, training and evaluation methods, and the strengths and limits of different approaches. Useful concepts include supervised and unsupervised learning, classification, regression, feature engineering, overfitting, and model evaluation.
A role focused on production systems may not require inventing new algorithms. However, engineers still need enough machine learning knowledge to implement models correctly, understand their limitations, and identify when their behavior may be unreliable.
Data and Infrastructure
Machine learning systems depend on data that is accurate, accessible, and appropriately managed. Engineers may work with databases, data processing frameworks, cloud platforms, containers, and distributed systems. They may also use tools for model tracking, workflow orchestration, deployment, and monitoring.
The specific technology stack depends on the organization. More important than knowing every tool is understanding how data and models move through a system, how to handle failures, and how to build processes that can be repeated and maintained.
Communication and Collaboration
Machine learning projects often involve people with different areas of expertise. An engineer may need to explain why a model is too slow for a particular product, clarify what data is available, or help a team choose between accuracy, cost, and response time. Clear communication helps teams make practical decisions and set realistic expectations.
How Machine Learning Software Engineering Differs from Data Science
Data scientists often focus on exploring data, testing hypotheses, and developing models or analyses. Machine learning software engineers generally focus on making software systems that can use those models reliably in production.
The responsibilities can overlap. At smaller organizations, one person may handle data analysis, model development, and deployment. At larger companies, these tasks may be divided among several specialized teams. The exact boundaries depend on the product and organization.
How to Become a Machine Learning Software Engineer
There is no single path into the field, but a strong foundation in software engineering is a practical starting point. A typical learning path may include:
- Learn programming fundamentals. Build confidence with a language commonly used for software or machine learning, such as Python.
- Develop core engineering skills. Practice data structures, algorithms, testing, APIs, databases, and version control.
- Study the math and concepts behind machine learning. Focus on statistics, probability, linear algebra, and foundational model concepts.
- Build complete projects. Go beyond training a model by creating an application or service that uses it.
- Learn deployment and monitoring. Explore how to package, serve, evaluate, and update models in a production-like environment.
- Share your work clearly. Document projects, describe design decisions, and explain how you measured results.
A degree in computer science, engineering, mathematics, or a related field can be helpful, but practical experience also matters. Personal projects, internships, research, and contributions to open-source software can demonstrate relevant skills.
Challenges in the Role
Machine learning systems introduce challenges beyond those found in many conventional applications. Data may be incomplete or change over time. A model that performed well in testing may behave differently in production. Predictions can also be difficult to explain, and small changes in a pipeline may affect results in unexpected ways.
Engineers must consider more than model accuracy. A successful system also needs appropriate safeguards, acceptable response times, reliable infrastructure, and responsible data practices. Depending on the application, privacy, fairness, security, and regulatory requirements may be essential parts of the work.
Career Outlook
Organizations across many industries are exploring ways to use machine learning, creating opportunities for engineers who can connect models with dependable software. Demand and job requirements vary by location and industry, and not every position uses the same tools or level of machine learning expertise.
For people interested in both building software and working with data-driven technology, machine learning software engineering can be a rewarding career. The strongest candidates combine sound engineering judgment with a practical understanding of machine learning—and keep learning as tools and techniques evolve.
6 Essential Tips for Software Engineers to Master Machine Learning
- Learn Python, SQL, and core machine learning concepts.
- Build projects with real-world datasets.
- Track experiments and version your data and models.
- Evaluate models with metrics that match the task.
- Deploy models with monitoring and clear rollback plans.
- Keep learning about new tools and techniques.
Learn Python, SQL, and core machine learning concepts.
Start by building a strong foundation in Python, SQL, and core machine learning concepts. Python is widely used to develop models and machine learning applications, while SQL helps you query, organize, and understand the data those systems depend on. Learn key ideas such as supervised and unsupervised learning, model training, evaluation, and overfitting. Together, these skills will help you contribute to machine learning projects and prepare you to build reliable, data-driven software.
Build projects with real-world datasets.
Build projects with real-world datasets to learn how machine learning works beyond clean, classroom examples. Real data often contains missing values, inconsistent formats, noise, or unexpected patterns, giving you practice with the preparation and troubleshooting required in real projects. Choose a dataset connected to a problem you care about, document your decisions, and evaluate your model with appropriate metrics. Then, if possible, turn your work into a small application or service to show how the model could be used in practice.
Track experiments and version your data and models.
Track every machine learning experiment, and version your data and models so you can reproduce results and understand what changed. Record key details such as the code version, dataset, model settings, evaluation metrics, and environment. When an outcome improves—or a model behaves unexpectedly—this history makes it easier to compare approaches, debug issues, and reliably roll back to a previous version.
Evaluate models with metrics that match the task.
Evaluate machine learning models with metrics that reflect the task and the cost of different mistakes. For example, accuracy can be misleading when one class is much more common than another; precision and recall may better show how well a model handles important positive cases. For regression, metrics such as mean absolute error or root mean squared error can reveal how far predictions are from actual values. Choose metrics based on how the model will be used, and review them alongside real-world constraints like latency, reliability, and the impact of incorrect predictions.
Deploy models with monitoring and clear rollback plans.
When deploying a machine learning model, set up monitoring to track performance, errors, latency, and changes in incoming data. Clear alerts can help the team catch problems before they affect many users. Create and test a rollback plan in advance so you can quickly restore a previous model or system version if the new deployment behaves unexpectedly. Together, monitoring and a reliable rollback process make releases safer and easier to manage.
Keep learning about new tools and techniques.
Machine learning tools and techniques evolve quickly, so make continuous learning part of your routine. Follow trusted industry publications, take courses, attend meetups, and experiment with new libraries or approaches through small projects. Focus not only on what a tool can do, but also on when it is useful and what tradeoffs it brings. Staying curious helps you make better technical decisions and build machine learning systems that are effective, reliable, and up to date.